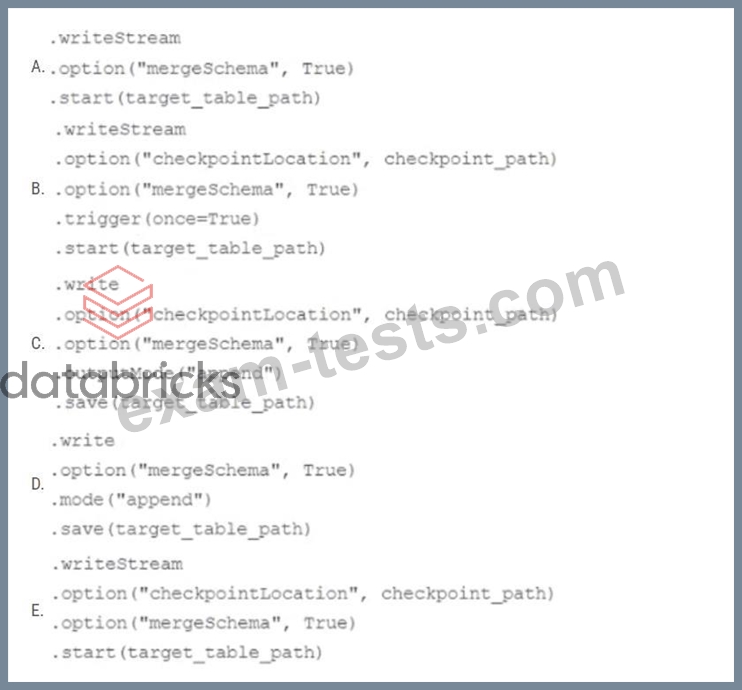
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected. The function is displayed below with a blank: Which response correctly fills in the blank to meet the specified requirements?
Correct Answer: B
Option B correctly fills in the blank to meet the specified requirements. Option B uses the "cloudFiles. schemaLocation" option, which is required for the schema detection and evolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References: * Configure schema inference and evolution in Auto Loader : https://docs.databricks.com/en/ingestion /auto-loader/schema.html * Write streaming data : https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming- data.html
Question 147
Which of the following describes a scenario in which a data engineer will want to use a Job cluster instead of an all-purpose cluster?
Correct Answer: D
Question 148
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States. The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed. Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
Correct Answer: C
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees. Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "Choose a region" section.
Question 149
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
Correct Answer: A
Explanation Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. References: https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
Question 150
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
Correct Answer: B
Explanation This is the best configuration for scheduling Structured Streaming jobs for production, as it automatically recovers from query failures and keeps costs low. A new job cluster is created for each run of the job and terminated when the job completes, which saves costs and avoids resource contention. Retries are not needed for Structured Streaming jobs, as they can automatically recover from failures using checkpointing and write-ahead logs. Maximum concurrent runs should be set to 1 to avoid duplicate output or data loss. Verified References: Databricks Certified Data Engineer Professional, under "Monitoring & Logging" section; Databricks Documentation, under "Schedule streaming jobs" section.