

Question 36
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
Question 37
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:

An analyze who is not a member of the auditing group executing the following query:
Which result will be returned by this query?
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
An analyze who is not a member of the auditing group executing the following query:
Which result will be returned by this query?
Question 38
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
Question 39
The data engineering team maintains the following code:
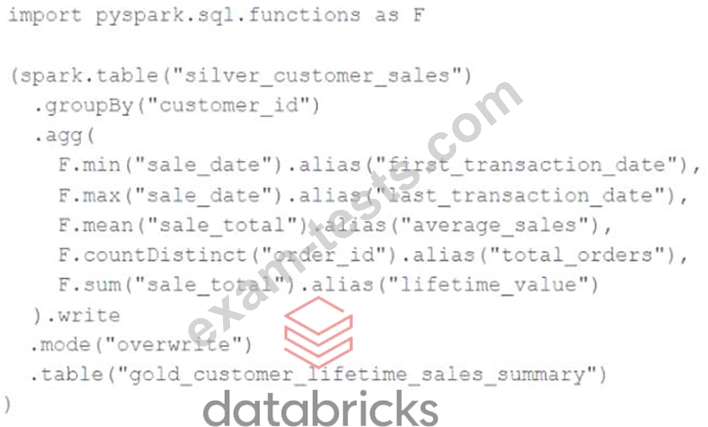
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Question 40
When working with AUTO LOADER you noticed that most of the columns that were inferred as part of loading are string data types including columns that were supposed to be integers, how can we fix this?