

Question 221
You are developing an ML pipeline using Vertex Al Pipelines. You want your pipeline to upload a new version of the XGBoost model to Vertex Al Model Registry and deploy it to Vertex Al End points for online inference. You want to use the simplest approach. What should you do?
Question 222
You are an ML engineer responsible for designing and implementing training pipelines for ML models. You need to create an end-to-end training pipeline for a TensorFlow model. The TensorFlow model will be trained on several terabytes of structured data. You need the pipeline to include data quality checks before training and model quality checks after training but prior to deployment. You want to minimize development time and the need for infrastructure maintenance. How should you build and orchestrate your training pipeline?
Question 223
You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?
Question 224
You developed a Vertex Al pipeline that trains a classification model on data stored in a large BigQuery table.
The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names:
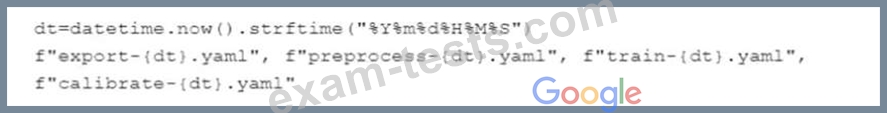
You launch your Vertex Al pipeline as the following:

You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?
The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names:
You launch your Vertex Al pipeline as the following:
You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?
Question 225
You are collaborating on a model prototype with your team. You need to create a Vertex Al Workbench environment for the members of your team and also limit access to other employees in your project. What should you do?
Premium Bundle
Newest Professional-Machine-Learning-Engineer Exam PDF Dumps shared by BraindumpsPass.com for Helping Passing Professional-Machine-Learning-Engineer Exam! BraindumpsPass.com now offer the updated Professional-Machine-Learning-Engineer exam dumps, the BraindumpsPass.com Professional-Machine-Learning-Engineer exam questions have been updated and answers have been corrected get the latest BraindumpsPass.com Professional-Machine-Learning-Engineer pdf dumps with Exam Engine here: