

Question 226
You want to train an AutoML model to predict house prices by using a small public dataset stored in BigQuery. You need to prepare the data and want to use the simplest most efficient approach. What should you do?
Question 227
Your company manages an application that aggregates news articles from many different online sources and sends them to users. You need to build a recommendationmodel that will suggest articles to readers that are similar to the articles they are currently reading. Which approach should you use?
Question 228
A Data Science team within a large company uses Amazon SageMaker notebooks to access data stored in Amazon S3 buckets. The IT Security team is concerned that internet-enabled notebook instances create a security vulnerability where malicious code running on the instances could compromise data privacy. The company mandates that all instances stay within a secured VPC with no internet access, and data communication traffic must stay within the AWS network.
How should the Data Science team configure the notebook instance placement to meet these requirements?
How should the Data Science team configure the notebook instance placement to meet these requirements?
Question 229
You are developing an ML model to identify your company s products in images. You have access to over one million images in a Cloud Storage bucket. You plan to experiment with different TensorFlow models by using Vertex Al Training You need to read images at scale during training while minimizing data I/O bottlenecks What should you do?
Question 230
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this:
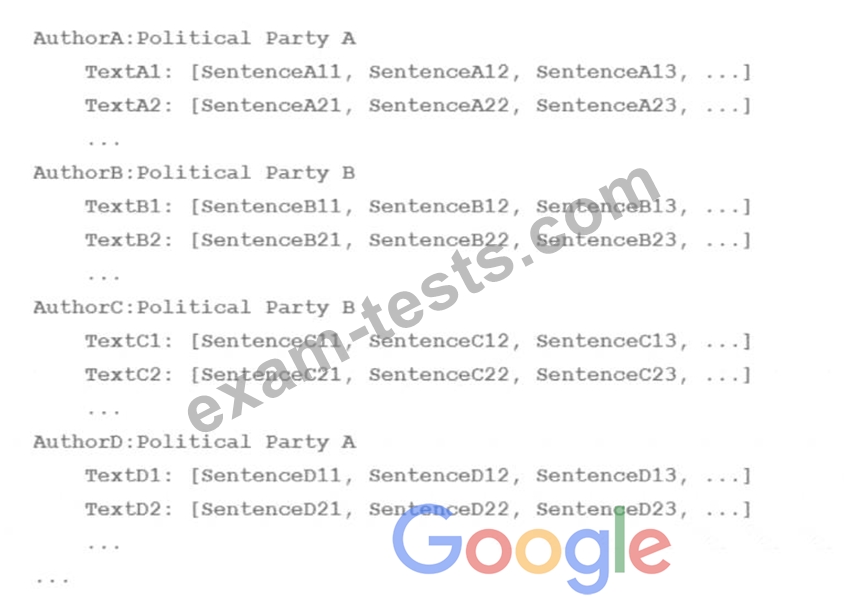
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets.
How should you distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion?
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets.
How should you distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion?
Premium Bundle
Newest Professional-Machine-Learning-Engineer Exam PDF Dumps shared by BraindumpsPass.com for Helping Passing Professional-Machine-Learning-Engineer Exam! BraindumpsPass.com now offer the updated Professional-Machine-Learning-Engineer exam dumps, the BraindumpsPass.com Professional-Machine-Learning-Engineer exam questions have been updated and answers have been corrected get the latest BraindumpsPass.com Professional-Machine-Learning-Engineer pdf dumps with Exam Engine here: